mercredi 3 septembre 2014

How to solve conflicts between different version of assemblies when deploying to Windows Azure Mobile Service

It's quite a long title but it says it all. When deploying to Windows Mobile Azure Service, the hosting environment has some pre-defined assemblies version that it likes to keep.

So if you've happily updated your nuget packages and all of the sudden your Azure Mobile Service site stops and in the logs you see:

Exception=System.IO.FileLoadException: Could not load file or assembly 'System.Web.Http, Version=5.2.2.0 etc....

Or

Found conflicts between different versions of the same dependent assembly 'System.Web.Http': 5.1.0.0, 5.2.2.0. Please change your project to use version '5.1.0.0' which is the one currently supported by the hosting environment.
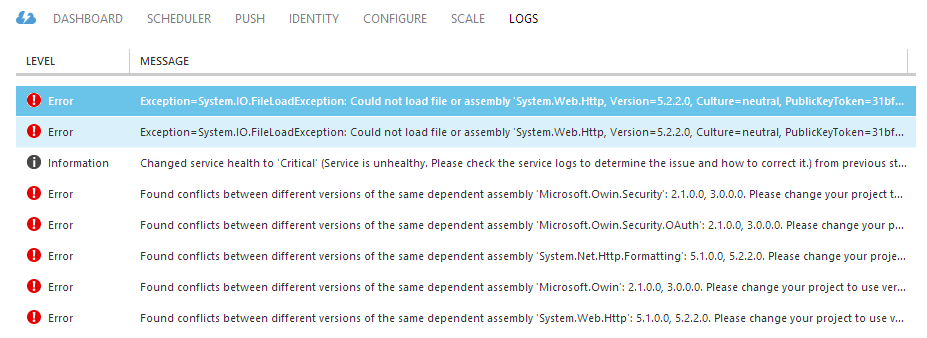
The kind of fun messages you'd get if you dare update those nuget packages


To solve that, we'll need to downgrade the nuget packages, which is no small feat. Obviously removing and re-adding the packages manually is out of the question; and we need a permanent solution to the package updating issue too.

Turns out NuGet 2.8 can help us with that. Here's an extract from the packages.config of the original (before the update) project.


The trick is to add a version constraint like so allowedVersions="[5.1.2]". It's all described on NuGet's documentation. Applying those constraints links to something like this:


Then it's just a matter of running Update-Package -reinstall to restore the packages to their right version... well not quite, for me it re-installed all the other packages in the projects in the solution, took a long time and spat a completely bogus solution that did not compile. The (much) longer approach is to update them one by doing something like:

Get-Project -All | ?{ $_ | Get-Package | ?{ $_.Id -eq 'Microsoft.AspNet.WebApi.Core' } } | %{ $_ | Update-Package Microsoft.AspNet.WebApi.Core -Reinstall }


Which is very tedious. Till next time, happy coding.

vendredi 24 janvier 2014

Windows Store C# Application: Reading a network stream

Here's a little snippet that will allow a Windows Store C# application send a command string to a server and then get a reply:

private async Task<string> DoCommand(string command)
{
    StringBuilder strBuilder = new StringBuilder();
    using (StreamSocket clientSocket = new StreamSocket())
    {
        await clientSocket.ConnectAsync(_serverHost, _serverPort);
        using (DataWriter writer = new DataWriter(clientSocket.OutputStream))
        {
            writer.WriteString(command);
            await writer.StoreAsync();
            writer.DetachStream();
        }
        using (DataReader reader = new DataReader(clientSocket.InputStream))
        {
            reader.InputStreamOptions = InputStreamOptions.Partial;
            await reader.LoadAsync(8192);
            while (reader.UnconsumedBufferLength > 0)
            {
                strBuilder.Append(reader.ReadString(reader.UnconsumedBufferLength));
                await reader.LoadAsync(8192);
            }
            reader.DetachStream();
        }
    }
    return (strBuilder.ToString());
}

What's important is the loop that will get the data until the end of the stream. This example is for a server that will reply some data and then close the connection; it's not suitable for an endless stream of data. I use this particular example to connect to CGMiner's api, where I send it a command string and it replies with some data, then close the connection.

mardi 14 janvier 2014

Windows Store & WCF Frustration

I was doing a nice & simple news app for the Windows Store in C# that uses WCF as its backend, and everything was going fine (by the book).

I created the Windows Store project, added Service Reference and started to code away happily. But at some point I decided to indicate in my WCF contract that my service can throw FaultExceptions.

It was already throwing FaultExceptions in some methods as part of its "normal" operation, and it was working fine (the Windows Store app was getting the FaultExceptions with all the metadata I attached) but I wanted to make it explicit for the other developers who were using my service to see which method threw FaultExceptions and which did not.

That was a very bad mistake that took an entire evening with the team to figure out: do not use FaultContract in your WCF service if your client is a Windows Store app. It will simply fail to generate the client proxy the next time you do an update service reference. That is the worst kind of error, because there could be some time between the moment you've added the FaultContract and the moment you  wonder where on Earth is your proxy client. And it does not even put out a message, warning or error when you update the service reference: it includes all the classes except the client proxy. A silent but deadly error.
And that lead us to a bug hunt where we re-created the Web.configs, created test projects trying to reproduce the bug, reverted files etc...

mercredi 7 août 2013

Nitro::Terrain Frustum Culling

I have progressed a bit on my terrain, I have brought back full dynamic lighting and frustum culling !
The lighting equations were from Shader X7 originally, and they model the Cook-Torrance lighting model which suits all my shading needs.

I had some concerns regarding the blending of different terrain materials (I'm doing a simple slope based material splatting), especially regarding the normals. I read this blog post about blending normals, and it got me thinking about how I should blend the normals of the different terrain materials.
I decided to test out some normal blending functions but none of them gave the expected results... the only thing that worked was when I added the two normals together !
float3 BlendNormals(float3 n1, float3 n2, float factor)
{
    return (normalize(float3(lerp(n1.xy, n2.xy, factor), n1.z*n2.z)));
}
I settled on something like the whiteout blend, except I needed to select how much of which normal to choose so I added the lerp; I'm not sure how that affects the accuracy of the result but it gives a decent enough normal for lighting.

Finally frustum culling makes a big comeback, I hadn't touched it since the last version of the terrain that used my home-cooked-ready-to-blow math functions. Well I say that but hey, it worked, so it wasn't broken and I shouldn't have touched it. My fault. But now that I've converted to XNA::Math let's keep rolling with it.
Turns out I was getting weird culling with just ComputeFrustumFromProjection (XNA::Math built-in), and true enough it was getting me a View Space frustum, so I had to convert it to a World Space frustum (transform it by the inverse of the view matrix). That's it, now frustum culling works !

That's an important step for the algorithms I plan on adding soon, which will require the terrain to be rendered multiple times from different perspectives (yes, shadow maps !).
Below you can find the code that computes the correct World frustum using XNA::Math (credit to this guy):

void CDLODTerrain::Prepare(Camera const &camera)
{
    _curtSelection = CDLODQuadTreeTerrain::LODSelection();
    XMFLOAT3 camPos;
    XMStoreFloat3(&camPos, camera.Position());
    XNA::Frustum frustum;
    XNA::Frustum worldFrustum;
    XMMATRIX projMat = camera.ProjectionMatrix();
    ComputeFrustumFromProjection(&frustum, &projMat);
    XMVECTOR scale, rotation, translation, detView;

    // The frustum is in view space, so we need to get the inverse view matrix
    // to transform it to world space.
    XMMATRIX invView = XMMatrixInverse(&detView, camera.ViewMatrix());

    // Decompose the inverse view matrix and transform the frustum with the components.
    XMMatrixDecompose(&scale, &rotation, &translation, invView);
    TransformFrustum(&worldFrustum, &frustum, XMVectorGetX(scale), rotation, translation);

    _curtViewingRange = camera.FarClip();
    _quadTree.LODSelect(camPos, worldFrustum, _curtViewingRange, _curtSelection);
}

The code is not optimized at all but it's correct and that's all that matters.
And below a video of the result:


mardi 6 août 2013

Continuous Level Of Detail terrain

I have recently re-started to work on my terrain engine from 2 years ago. This time it's DX11 only, and I've managed to finally get the geometry just right.

The problems:
I had been battling with the vertices for so long, not exactly sure what was causing all the artifacts I was having: stripes, background appearing in front of foreground objects, vertex being culled for (apparent) no reason and finally holes in the geometry (patch).

The first one (the stripes) and second one were due to not setting depth writes (duh, I was tired), I finally caught that after plowing through dozens of rasterizer states. My objects (terrain tiles) were actually sorted from front to back so the bug was somewhat hard to track.

It was certainly not helped by the wrong vertex winding order (I should have read the doc more carefully): I always wind my vertices in counter-clockwise fashion (maybe an old OpenGL habit). But in DirectX 11 it's not the default, so I turned "counter clockwise is front" to true in the rasterizer.

That was not the end of the road, as the code to draw the terrain patches was very old and back then I was very much debuting my programming career; so not so many comments, lots of "magic" values and a questionable sense of object orientation. Which means now that my patches were drawing I had one triangle missing in each quad. Turns out I had a similar problem on an OpenGL game I developed for Epitech recently (the R-Type) and it had to do with the index size.

Short version is: check that the number of vertices you store in those vertex buffers are < 65536 if you are going to use DXGI_FORMAT_R16_UINT, and don't hard code that enum, but make it dynamic so that if you have less than those vertices you can enjoy a smaller buffer, while when you go over that you switch seamlessly to R32_UINT.

The implementation:
I chose MJP's framework to rebase my algorithm, so that I have a solid base to start off. The algorithm is based on Philip Strugar's paper on CDLOD terrain and I've adapted a few things to make it simpler to implement (at least for me), as I was trying to get it working before trying to optimize it.

So what's the result ? Here's a video showing what I have so far:


Next I'll be working on the shading of the terrain, and making it larger. I'm deciding between two routes for the texturing technique: one massive texture (think 16kx16k +) that is broken down in mip-maps that are paged in when required (a la Rage but not quite) or a procedural texture splatting technique which is a classic in this domain.
Personally, the procedural texture is going to be easier to implement at first, and it would be a nice complement to a procedural terrain. Then I should be able to add a mega texture on top for all those unique features an artist would want to put in.

jeudi 27 juin 2013

Skyrim & ATI Radeon GPU

This is an odd post in the hopes it might help someone.

I have spent the last year or so trying to get some of my games to work on my new Windows 8 gaming rig and I recently managed to get Skyrim going again.

The issue was that in the Skyrim installation folder (under Steam that is C:\Program Files (x86)\Steam\steamapps\common\skyrim) there was 2 DLLs: atimgpud.dll and atiumdag.dll.

I'm not sure how that got here, I usually don't mess with my installation folders but I've had this game for a long time and whenever I get a new system I just copy the whole steamapps folder.

So I just erased the two files and that fixed the "Failed to initialize renderer: Unknown error" that I was having.

Now on to slaying some dragons.

mercredi 11 juillet 2012

Upgrading mid-2009 MacBook Pro 13"

Editorial: I have just came back to this blog after a long period of absence due to some major life events (moving out of Australia) and I found this post still a draft, from approximately August 2011; since I did spend the time writing it, I might as well post it. So here it is folks, the first post since I'm back is a post from the past.

I've just come back from France where I celebrated my birthday a few weeks ago.
Amongst my presents was a Western Digital 2.5" Scorpio Blue 1TB hard drive and a G.Skill DDR3 SO-DIMM 8GB (2x4GB) kit for my MacBook Pro. (yeah I'm a nerd :P)
So of course I had to document the entire procedure and take pictures of everything !
The upgrade was not all that smooth (I blame Apple, see next post) but I've got it all (almost) working.

Now of course doing these kind of modifications to your computer yourself will certainly void your warranty, may cause irreversible damage to your computer etc... do it at your own risk !

OK, Let's start by taking this baby apart shall we ?
All we need is a small philips screwdriver and a small torn screwdriver (for the hard drive) as seen on the next picture:


Don't forget to use your anti-static strap if you have one, otherwise don't forget to touch some metal part of your computer to discharge yourself of any static you may be carrying.
Failure to do so may result in damage to your computer, especially to the RAM which is very sensitive to static. I attached my anti-static strap to some metal par at the back of my desktop computer case.


Next, lie the MBP upside down (face with the Apple logo down) on some soft surface (to avoid scratching it !) and unscrew the 10 screws holding the back plate (7 shorts, 3 longs).
To remember where each went I placed them in the order I took them out, see the following pic:


Once the screws are off, the plate should come off easily; put it aside.
I'll start by upgrading the HDD.
I've read some comments on the internet about how the new 1TB HDD are too big for the MBP (12.5mm), and it won't fit. I have to say it is true that it's quite big compared to the original one (see pic):


However it fits perfectly, and I have had no trouble at all installing it.
So start by un-tightening the two screws holding the HDD bracket in place:


Then remove and store that bracket with its two screws somewhere safe.
Next, pull the transparent tape slowly to get the HDD out:


You will need to remove the connector that goes to the logic board:
To do that, just insert your nail (or something of the sort), in between the connector and the HDD, and pull slightly away from the HDD until the connector becomes loose:


There are 4 (four) mounting screws around the HDD, and if your new HDD did not come with some attached (mine did not) you will have to transfer them across. This is where you need your torx screwdriver, the position of the 4 screws are circled in red in the following picture:


Screw them back onto your new HDD and you're ready to continue:


Now store that old HDD somewhere safe; in my case I will use it later to restore my mac during the install of OS X.
Put the logic board connector on the new HDD, and place it down.


Replace the HDD mounting bracket:


And you're done for the HDD !

mercredi 4 mai 2011

Generating normals on the GPU from a height map

While reading Shader X7 I stumbled upon the article "Dynamic Terrain Rendering on GPUs Using Real-Time Tessellation" (if you don't have Shader X7 yet, get it from amazon, it's a must-read).

In the article, Natalya Tartarchuk describes a way to shader such dynamic terrain that computes the normal on-the-fly.
This is very interesting since it could allow one to dynamically modify the height map and have the normals adjust automatically.
After spending a few hours debugging the normals I finally got something visually pleasing, although I've noticed a few artifacts.
After some more testing I've noticed that there is some error involved in computing the normals on the GPU (compared to the reference algorithm on the CPU).

The first image is the reference image, the normals have been generated on the CPU using the central difference algorithm.
In order to visualize the normals, they are moved into the [0,1] range by doing Normal * 0.5 + 0.5:

Reference normals generated on the CPU

The second picture is ATI's algorithm running on the pixel shader.
I had to tweak some of their variable since it seemed to rely on "magic" (but documented) value:

ATI's algorithm

The following picture shows the error between the normals computed as GPUNormal - CPUNormal:

Divergence from CPU normals. Grey areas mean error = 0 (since 0 * 0.5 + 0.5 = 0.5).

The third picture is the central difference algorithm ported on the GPU and running in the pixel shader.

The normals generated by the central difference algorithm in the pixel shader

The resulting error

My implementation of the central difference algorithm on the GPU must be pretty bad considering the divergence. I also tried the two algorithms on the vertex shader but sadly the error was just too great (except on the flat plane).

Now the question is, is it worth it to generate the normals on the GPU ?
I would say, if you're not having a dynamic terrain, you're better off with the normals on the CPU since it leads to much greater visual quality and won't steal one of those precious sampler slot so needed on SM3 hardware.
One advantage of generating the normals on the fly could be to reduce the size of the vertex buffer (take out normal + tangent from the vertex declaration => up to 6 floats per vertex removed) but that is to be balanced with the size of the height map.

mercredi 16 mars 2011

Circumventing the C# reference to reference problem

Recently I have been working on a simple recursive descent parser in C# .Net 4.0 and I encountered an error I did not expect; the following is not valid C#:

Rule integer, factor, expression, term;

integer = +Parser.digit_p();
   
factor = integer
 | Parser.ch_p('(') + expression + Parser.ch_p(')')
 | (Parser.ch_p('-') + factor)
 | (Parser.ch_p('+') + factor);
term = factor *((Parser.ch_p('*') + factor) | (Parser.ch_p('/') + factor));
expression = term * ((Parser.ch_p('+') + factor) | (Parser.ch_p('-') + factor));

This makes sense because we cannot use the rules before they have been initialized !
In C++ we'd just take a reference or pointer to the rule until they are defined; but this does not work in C#.

Instead I had to create a simple RuleRef class as follow:
public class RuleRef
{
 private Rule ptr;

 public Rule Value
 {
  get
  {
   return ptr;
  }

  set
  {
   ptr = value;
  }
 }

 public static implicit operator Rule(RuleRef r)
 {
  return r.Value;
 }

 public RuleRef()
 {

 }

 public RuleRef(Rule value)
 {
  ptr = value;
 }

 public static RuleRef operator +(RuleRef lhs, RuleRef rhs)
 {
  return new Sequence(lhs, rhs);
 }

 public static RuleRef operator +(RuleRef lhs)
 {
  return new OneOrMore(lhs);
 }

 public static RuleRef operator |(RuleRef lhs, RuleRef rhs)
 {
  return new Or(lhs, rhs);
 }

 public static RuleRef operator &(RuleRef lhs, RuleRef rhs)
 {
  return new Sequence(lhs, rhs);
 }

 public static RuleRef operator *(RuleRef lhs, RuleRef rhs)
 {
  return new Sequence(lhs, new ZeroOrMore(rhs));
 }
}

This allow me to then write:
RuleRef integer = new RuleRef();
RuleRef factor = new RuleRef();
RuleRef expression = new RuleRef();
RuleRef term = new RuleRef();

integer = +Parser.digit_p();
   
Rule _factor = integer.Value.WithAction(DebugPrint)
 | Parser.ch_p('(') + expression + Parser.ch_p(')')
 | (Parser.ch_p('-') + factor)
 | (Parser.ch_p('+') + factor);

Rule _term = factor *((Parser.ch_p('*') + factor) | (Parser.ch_p('/') + factor));

Rule _expression = term * ((Parser.ch_p('+') + factor) | (Parser.ch_p('-') + factor));

// Resolve the references to their correct values
factor.Value = _factor;
term.Value = _term;
expression.Value = _expression;

In the next post I will detail my simple recursive descent parser entirely written in C#/Linq.

lundi 13 décembre 2010

API independent primitive topology

Here is a simple uber function for retrieving the primitive topology in a native API format from an API independent format:

enum PrimitiveTopology
{
 PT_POINTS = 0,
 PT_LINES,
 PT_LINE_STRIP,
 PT_TRIANGLES,
 PT_TRIANGLE_STRIP,
 PT_TRIANGLE_FAN,
 PT_QUADS,
 PT_QUAD_STRIP
};

enum GraphicsAPI
{
 DirectX11,
 DirectX10,
 DirectX10_1,
 DirectX9,
 OpenGL,
 OpenGLES
};

template <GraphicsAPI API>
int getPrimitiveTopology(PrimitiveTopology pt)
{
 switch (API)
 {
  case DirectX11:
  case DirectX10:
  case DirectX10_1:
   switch(pt)
   {
    case PT_POINTS:
     return D3D_PRIMITIVE_TOPOLOGY_POINTLIST;
     break;
     
    case PT_LINES:
     return D3D_PRIMITIVE_TOPOLOGY_LINELIST;
     break;
     
    case PT_LINE_STRIP:
     return D3D_PRIMITIVE_TOPOLOGY_LINESTRIP;
     break;
     
    case PT_TRIANGLES:
     return D3D_PRIMITIVE_TOPOLOGY_TRIANGLELIST;
     break;
     
    case PT_TRIANGLE_STRIP:
     return D3D_PRIMITIVE_TOPOLOGY_TRIANGLESTRIP;
     break;
     
    case PT_TRIANGLE_FAN:
     return D3D_PRIMITIVE_TOPOLOGY_UNDEFINED;
     break;
     
    default:
     assert(0 && "getPrimitiveTopology::DirectX10+ Unknown or unsupported primitive topology !");
     return -1;
     break;
   }
   break;
  case DirectX9:
   switch(pt)
   {
    case PT_POINTS:
     return D3DPT_POINTLIST;
     break;
     
    case PT_LINES:
     return D3DPT_LINELIST;
     break;
     
    case PT_LINE_STRIP:
     return D3DPT_LINESTRIP;
     break;
     
    case PT_TRIANGLES:
     return D3DPT_TRIANGLELIST;
     break;
     
    case PT_TRIANGLE_STRIP:
     return D3DPT_TRIANGLESTRIP;
     break;
     
    case PT_TRIANGLE_FAN:
     return D3DPT_TRIANGLEFAN;
     break;
     
    default:
     assert(0 && "getPrimitiveTopology::DirectX9 Unknown or unsupported primitive topology !");
     return -1;
     break;
   }
   break;
  case OpenGL:
  case OpenGLES:
   switch(pt)
   {
    case PT_POINTS:
     return GL_POINTS;
     break;
     
    case PT_LINES:
     return GL_LINES;
     break;
     
    case PT_LINE_STRIP:
     return GL_LINE_STRIP;
     break;
     
    case PT_TRIANGLES:
     return GL_TRIANGLES;
     break;
     
    case PT_TRIANGLE_STRIP:
     return GL_TRIANGLE_STRIP;
     break;
     
    case PT_TRIANGLE_FAN:
     return GL_TRIANGLE_FAN;
     break;
    default:
     assert(0 && "getPrimitiveTopology::OpenGL/ES Unknown or unsupported primitive topology !");
     return -1;
     break;
   }
   break;
  default:
   assert(0 && "getPrimitiveTopology() Unknown API !");
   return -1;
   break;
 }
}


A good compiler should optimize the dead code.
Also if you want to avoid the dependency on the graphics API headers, here are the necessary enums:


enum D3D_PRIMITIVE_TOPOLOGY
{
 D3D_PRIMITIVE_TOPOLOGY_UNDEFINED = 0,
 D3D_PRIMITIVE_TOPOLOGY_POINTLIST = 1,
 D3D_PRIMITIVE_TOPOLOGY_LINELIST = 2,
 D3D_PRIMITIVE_TOPOLOGY_LINESTRIP = 3,
 D3D_PRIMITIVE_TOPOLOGY_TRIANGLELIST = 4,
 D3D_PRIMITIVE_TOPOLOGY_TRIANGLESTRIP = 5
};

enum D3DPRIMITIVETYPE
{
 D3DPT_POINTLIST = 1,
 D3DPT_LINELIST = 2,
 D3DPT_LINESTRIP = 3,
 D3DPT_TRIANGLELIST = 4,
 D3DPT_TRIANGLESTRIP = 5,
 D3DPT_TRIANGLEFAN = 6,
 D3DPT_FORCE_DWORD = 0x7fffffff,
};

enum GLPrimitiveTopology
{
 GL_POINTS                        = 0x0000,
 GL_LINES                         = 0x0001,
 GL_LINE_LOOP                     = 0x0002,
 GL_LINE_STRIP                    = 0x0003,
 GL_TRIANGLES                     = 0x0004,
 GL_TRIANGLE_STRIP                = 0x0005,
 GL_TRIANGLE_FAN                  = 0x0006,
 GL_QUADS                         = 0x0007,
 GL_QUAD_STRIP                    = 0x0008,
 GL_POLYGON                       = 0x0009,
};

If you define the native types yourself, watch out for conflicts !

lundi 11 octobre 2010

What do programmers do when they are bored ?

Ok so I have not posted in a long time because I've been very busy with my uni stuff; so I thought I might share a nice little trick I developed quickly this morning.

Yes I was very bored and skimming through DXUT source file when I spotted those:
#define SET_ACCESSOR( x, y )       inline void Set##y( x t )   { DXUTLock l; m_state.m_##y = t; };
#define GET_ACCESSOR( x, y )       inline x Get##y()           { DXUTLock l; return m_state.m_##y; };
#define GET_SET_ACCESSOR( x, y )   SET_ACCESSOR( x, y ) GET_ACCESSOR( x, y )

#define SETP_ACCESSOR( x, y )      inline void Set##y( x* t )  { DXUTLock l; m_state.m_##y = *t; };
#define GETP_ACCESSOR( x, y )      inline x* Get##y()          { DXUTLock l; return &m_state.m_##y; };
#define GETP_SETP_ACCESSOR( x, y ) SETP_ACCESSOR( x, y ) GETP_ACCESSOR( x, y )

and I instantly wanted the same type of macros, except with all the genericity and safety of C++0x.

Setters were a walk in the park:
#define Nitro_PropertySet(name)    inline void set##name(decltype(m##name) t) { m##name = t; }

Getters not so much; I initially thought that I could use the trailing-type feature of C++0x to get an auto-magic return type, unfortunately it behaves differently and would not accept the member name for an answer.
So I used a little trick, I declare a template structure with a default template parameter (the decltype with the member name), add a typedef, inject the whole in the inline getters and there it is !

#define Nitro_PropertyGet(name)    template < typename T = decltype(m##name)> struct __##name { typedef typename T type; }; inline __##name<>::type get##name() { return m##name; }

For a member named mNumSplits, that expands to:
 template < typename T = decltype(mNumSplits)>
 struct __mNumSplits { typedef typename T type; };
 inline __mNumSplits<>::type getNumSplits() { return mNumSplits; }

Neat. And all that while eating breakfast :)

mercredi 1 septembre 2010

A horrible hack turned safe thanks to templates.

While coding some shader implementation for DirectX 11 I found myself writing the same code over and over for each shader type (Vertex, Fragment, Geometry, Hull, Domain etc...) and I figured I should make it more generic.

The only problem is that Direct3D 11 has a separate function to create each type of shader, so in order to make it generic I originally came up with a solution which I qualify as "horrible hack".

In DirectX 11 the ID3D11Device has some methods like:
HRESULT __stdcall ID3D11Device::CreateVertexShader(
    [in]   const void *pShaderBytecode,
    [in]   SIZE_T BytecodeLength,
    [in]   ID3D11ClassLinkage *pClassLinkage,
    [out]  ID3D11VertexShader **ppVertexShader);


    HRESULT __stdcall ID3D11Device::CreatePixelShader(
    [in]   const void *pShaderBytecode,
    [in]   SIZE_T BytecodeLength,
    [in]   ID3D11ClassLinkage *pClassLinkage,
    [out]  ID3D11PixelShader **ppPixelShader
    );

And ID3D11VertexShader and ID3D11PixelShader are both inheriting publicly from ID3D11DeviceChild:

ID3D11VertexShader : public ID3D11DeviceChild { ... }
    ID3D11PixelShader : public ID3D11DeviceChild { ... }

Now the trick was to define a function pointer CreateShader that has the following prototype:

typedef HRESULT (__stdcall ID3D11Device::*CreateShader)(const void *,SIZE_T, ID3D11ClassLinkage*,ID3D11DeviceChild**);

The only difference is the last argument which points to the superclass of the shader classes.
Now I only have to pass this function pointer pointing to the right method of the ID3D11Device when I create my shader.
The problem with that is that I have to pass the shader as its base type, which is supposed to work according to the rules of C++ except, however the (wise) compiler complained when I tried to do it implicitly.
That forced me to create a ID3D11DeviceChild* and assign the ID3D11*Shader to it, then pass it to the method.
In other word it look even more horrible; that's where templates come to help.

I decided to template the loadShader method, and use the shader type to select the appropriate ID3D11::Create* method.
Since function templates cannot have defaults, I created a helper structure:

template <class Shader>
struct CreateShaderHelper
{
 typedef typename HRESULT (__stdcall ID3D11Device::*FuncType)(const void *,SIZE_T, ClassLinkage*,Shader**);
};
Now I can re-write the loadShader method like this:

template <class Shader>
int loadShader(const char* name,
        const char* defines,
        const char* profile,
        typename CreateShaderHelper<Shader>::FuncType shader_creator,
        ConstantBuffer& cbuff,
        Shader*& outShader,
        ID3D11ShaderReflection*& outShaderReflect)
{
    ...
    if ((device->*shader_creator)(shader_buffer->GetBufferPointer(),shader_buffer->GetBufferSize(),&outShader) == S_OK)
    {
         ...
    }
}

lundi 30 août 2010

RenderTarget or Camera centric engine design ?

The engine I'm currently working on has a RenderTarget centric design, a lot like Ogre's.
A RenderTarget centric design means that all the rendering is done around RenderTargets:
The rendering window is a render target, the shadow maps are render targets etc...

Essentially a render target can have viewports, and each viewport has a camera.
This is good for doing things like multi-viewports views in games (like split screens), and it's easy to just add a viewport to a render target and configure a camera for it.
An advantage of this technique is that it minimizes render target changes, you set the render target, collect all viewports and cameras associated with it, then get all the visible objects and render them; rince repeat.
Obviously the downside is a lot of changes in camera matrices and viewports.

Recently I have acquired the book Game Engine gems 1, and in particular the gem by Colt McAnlis from Blizzard Entertainment caught my attention.
He describes a camera-centric engine design for multi-threaded rendering.
In his design everything is a camera and his association is done via a RenderView structure:
The RenderView struct groups the camera, frustum, render target and all the rendering commands.
This allows him to build drawing command buffers in parallel and then submit them to the API, grouped to minimize state changes.

At first I was bit against his design (after all we're all a bit reluctant to changes especially after working so long on a different design that does the job), but I realized that a camera-centric approach might facilitate dealing with things like portal-rendering which my design didn't account for at all.
That doesn't mean it's not possible to do with my current engine, just that I didn't think of that and I believe that a camera-centric design makes more sense; every camera contribute their view data to the final scene, including portal cameras.

In conclusion, RenderTarget centric design starts from a render target and move toward cameras, whereas camera-centric designs move from cameras to render targets.
Both design are good, and help structure the rendering engine, but a camera-centric design might reflect more how we think about cameras in real life; at least compared to the RenderTarget design which might seem backwards.

jeudi 5 août 2010

Hot config for people looking to spend big

If you are thinking of upgrading or buying a new computer, have a load of cash, and want to be future proof for a while (read >= 5 years) then this configuration would suit you:

Motherboard:EVGA Classified Super Record 2 (SR-2) about AUD1000
Processors: 2x Intel Xeon X5680 Gulftown, 3.33GHz, Six Core hyper-threaded about AUD2000 each
RAM: 12 hand-picked, hand-tested DIMMs, 48GB of ultra-high capacity at 1,900MHz, CL8 G.Skill Ripjaws
Power Supply: Thermaltake ToughPower 1500W PSU about AUD500
GPUs: 4x ATI Radeon HD5870 2GB OR 2x ATI Radeon HD5970 2GB (optional 1x Nvidia GTX480 (PhysX + 3D)) roughly AUD2000

And that does not even include the case (which will have to specifically support that over-sized HPTX motherboard) nor its cooling.
For a case (that does not exist yet), have a look at Mick64's dream case on extreme system or this Lian Li case.

And if you do build something like that, don't forget to post pictures and brag about it in forums, you deserve it :)

vendredi 23 juillet 2010

Mouse ballistics and OS X

Tonight I finished downloading CounterStrike:Source on my Mac
and thought of playing for a few hours, to see how it goes.

First impression was good, the game ran ok on my MacBook Pro 15" (with an Nvidia 9400M I don't expect miracles anyway), but then it happened: I kept on getting fragged after putting half of my clip in the environment (Player vs Environment took all its sense) instead of on the bad guys.

That was the last straw, I've had enough of the ridiculous mouse ballistics on OS X that literally ruined my game (I know it's an easy excuse to blame the OS =P, but trust me it was frustrating not even to mention painful).

The problem is that an operating system does not serve raw mouse value to its program (although you can access it), but applies what is called "ballistics" to the pointer (also known as mouse acceleration curve).

The ballistics applied determines precisely how a mouse "handles", and that's why the same mouse behaves differently under OS X, Windows or Linux (however some people report not noticing a difference).

On OS X, I found that the mouse feels sticky, I have to yank it a bit to get it to move.
And since I have to make such an abrupt movement to compensate for the stickiness,
I tend to overshoot the target when the mouse starts flying across the screen.
No matter how hard or often I try, I either overshoot, or stop too soon.
And that's not only in games, I often catch myself cursing after misplacing the caret in XCode, or clicking on the close button of a window instead of minimising.
It appears Apple brought this shame on its OS only recently, and I wish they fix it (as it's clearly broken); or at least bring the option to change the feel of the mouse.

Note that this applies only to external mice that I connect to my Mac, the built-in trackpad feels just right, and I usually use it instead; but then again how am I going to frag with a track pad ?

vendredi 16 juillet 2010

Hello World

Hello and welcome,

Every programmer learning a new language starts with some form of Hello World program; here's mine, although blogspot is no new language (English would be):

std::cout << "Hello and welcome"  << std::endl;

Seriously though, I intend to use this space to post my thought and comments mostly about technology, coding (especiallty C-based languages) and maybe a personal thing or two there and there as well.

Till next post, exit(0);